NVIDIA · Volta · 32 GB · Qwen3.8 27B · Q4_K_M: ~34 tok/s
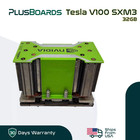
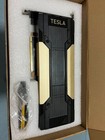
NVIDIA Tesla V100 32GB SXM
32 GB of HBM2 at 900 GB/s for well under a PCIe V100: SXM2 modules from DGX-1 and SXM3 modules from DGX-2 both run on Chinese adapter boards. Buy the board that matches the module. CUDA 13 dropped Volta, so stay on CUDA 12 builds.
Lowest price right now
$470
eBay · $450 + $20 shipping · $14 per GB · observed 2026-10-18 19:13 UTC
plus an SXM2 or SXM3 adapter, about $200 to $300
Buy the cheapest on eBay, $470
$450 + $20 shipping · Used · spareitllc 2,569 · 99.9%
Price alert
One email per move, item plus shipping. Clear the price to hear about any drop. Manage alerts.
Price history
Tracking started today. The chart appears once there is a second day of data.
Where to buy
| Vendor | Price | Condition | Observed | |
|---|---|---|---|---|
| eBay cheapest active listing |
$470 $450 + $20 shipping |
new and used | 2026-10-18 19:13 UTC | Go to eBay |
On eBay now
159 listings passed our filters at the last check. Cheapest delivered first. Seller reputation is feedback count and positive rate.
-
 $470$450 + $20 shipping
-
 $593.15$570 + $23.15 shipping
-
 $599free shipping
-
 $699free shipping
-
 $744free shipping
-
 $777.97$775 + $2.97 shipping
What it runs
For each model, grouped by vendor with the newest first: the largest quant that fits with 8K of context and the estimated speed for one user, at 8K and at 32K of context. On a card, a model too big for its memory can still run with part of the weights in system RAM; we assume 64 GB, and the speed shown accounts for it. The model you picked on the ladder is highlighted. Estimates from the spec sheet, not measurements: see how we estimate.
| Model | Quant | Needs at 8K | Fit | Max context | Decode at 8K | At 32K | Prefill tok/s |
|---|---|---|---|---|---|---|---|
| DeepSeek | |||||||
| DeepSeek V4.1 Flash 552B-A16B Sep 2026 | Q4_K_M | 338 GB | does not fit | ||||
| DeepSeek V4 Flash 284B-A13B Jul 2026 | Q4_K_M | 175 GB | does not fit | ||||
| DeepSeek V3.1 671B-A37B Aug 2025 | Q4_K_M | 411 GB | does not fit | ||||
| Gemma | |||||||
| Gemma 4 12B May 2026 | Q8_0 | 14 GB | fits | 128K+ | ~46 | ~44 | ~1,800 |
| Gemma 4 31B Mar 2026 | Q6_K | 27 GB | fits | 63K | ~23 | ~21 | ~710 |
| Gemma 4 26B-A4B Mar 2026 | Q8_0 | 28 GB | fits | 128K+ | ~94 | ~87 | ~5,800 |
| Gemma 3 27B Mar 2025 | Q8_0 | 31 GB | fits | 17K | ~20 | ~800 | |
| GLM | |||||||
| GLM-5.3 753B-A40B Aug 2026 | Q4_K_M | 462 GB | does not fit | ||||
| GLM-5.3 Flash 320B-A18B Aug 2026 | Q4_K_M | 197 GB | does not fit | ||||
| GLM-4.6 355B-A32B Sep 2025 | Q4_K_M | 221 GB | does not fit | ||||
| GLM-4.5 Air 106B-A12B Jul 2025 | Q4_K_M | 68 GB | runs with 36 GB in system RAM | ~9.0 | ~7.6 | ~910 | |
| gpt-oss | |||||||
| gpt-oss-120b Aug 2025 | Q4_K_M | 73 GB | runs with 42 GB in system RAM | ~20 | ~18 | ~2,100 | |
| gpt-oss-20b Aug 2025 | Q8_0 | 24 GB | fits | 128K+ | ~93 | ~78 | ~6,100 |
| Llama | |||||||
| Llama 4 Scout 109B-A17B Apr 2025 | Q4_K_M | 70 GB | runs with 38 GB in system RAM | ~6.3 | ~5.4 | ~640 | |
| Llama 3.3 70B Dec 2024 | IQ2_M | 28 GB | fits | 19K | ~22 | ~310 | |
| Llama 3.1 8B Jul 2024 | Q8_0 | 11 GB | fits | 128K+ | ~61 | ~46 | ~2,700 |
| MiMo | |||||||
| MiMo V2.6 Pro 1.02T-A42B Sep 2026 | Q4_K_M | 624 GB | does not fit | ||||
| MiMo V2.6 Flash 309B-A15B Sep 2026 | Q4_K_M | 190 GB | does not fit | ||||
| Mistral | |||||||
| Mistral Medium 3.5 128B Mar 2026 | Q4_K_M | 83 GB | runs with 51 GB in system RAM | ~0.8 | ~85 | ||
| Mistral Small 4 119B-A6.5B Mar 2026 | Q4_K_M | 79 GB | runs with 47 GB in system RAM | ~13 | ~1,700 | ||
| Mistral Small 3.2 24B Jun 2025 | Q8_0 | 28 GB | fits | 30K | ~22 | ~910 | |
| Nemotron | |||||||
| Nemotron 3.5 Lightning 30B-A3B Aug 2026 | Q6_K | 27 GB | fits | 128K+ | ~120 | ~110 | ~6,300 |
| Qwen | |||||||
| Qwen3.8 Flash-Next 125B-A6B Aug 2026 | Q4_K_M | 78 GB | runs with 46 GB in system RAM | ~16 | ~16 | ~1,800 | |
| Qwen3.8 27B Aug 2026 (your pick) | Q8_0 | 31 GB | fits | 28K | ~20 | ~810 | |
| Qwen3.6 27B Apr 2026 | Q8_0 | 31 GB | fits | 28K | ~20 | ~810 | |
| Qwen3.6 35B-A3B Apr 2026 | Q6_K | 30 GB | fits | 85K | ~130 | ~110 | ~7,300 |
| Qwen3.5 9B Feb 2026 | Q8_0 | 11 GB | fits | 128K+ | ~60 | ~55 | ~2,400 |
| Qwen3 Coder 480B-A35B Jul 2025 | Q4_K_M | 296 GB | does not fit | ||||
| Qwen3 235B-A22B Jul 2025 | IQ2_M | 83 GB | runs with 51 GB in system RAM | ~7.8 | ~6.8 | ~500 | |
| Qwen3 32B Apr 2025 | Q6_K | 31 GB | fits | 13K | ~20 | ~670 | |
Specifications
- Memory
- 32 GB HBM2
- Memory bandwidth
- 900 GB/s
- Bus width
- 4096-bit
- Shader cores
- 5,120
- Tensor cores
- 640
- FP32
- 15.7 TFLOPS
- FP16 (dense)
- 125 TFLOPS
- Power
- 300 W
- Form factor
- SXM2 or SXM3 module: needs a matching adapter board and a fan
- Interface
- PCIe 3.0 x16
- Architecture
- Volta
- Launched
- 2018
Source: manufacturer specifications.
Embed the live price
A badge that always shows the current eBay low for the V100 32GB SXM, delivered, and links back here. Free to use in a README, a forum signature or a blog post.
HTML and Markdown snippets
<a href="https://buyaigear.com/gpus/tesla-v100-32gb-sxm"><img src="https://buyaigear.com/badge/tesla-v100-32gb-sxm.svg" alt="V100 32GB SXM: live eBay low" height="20"></a>
[](https://buyaigear.com/gpus/tesla-v100-32gb-sxm)